
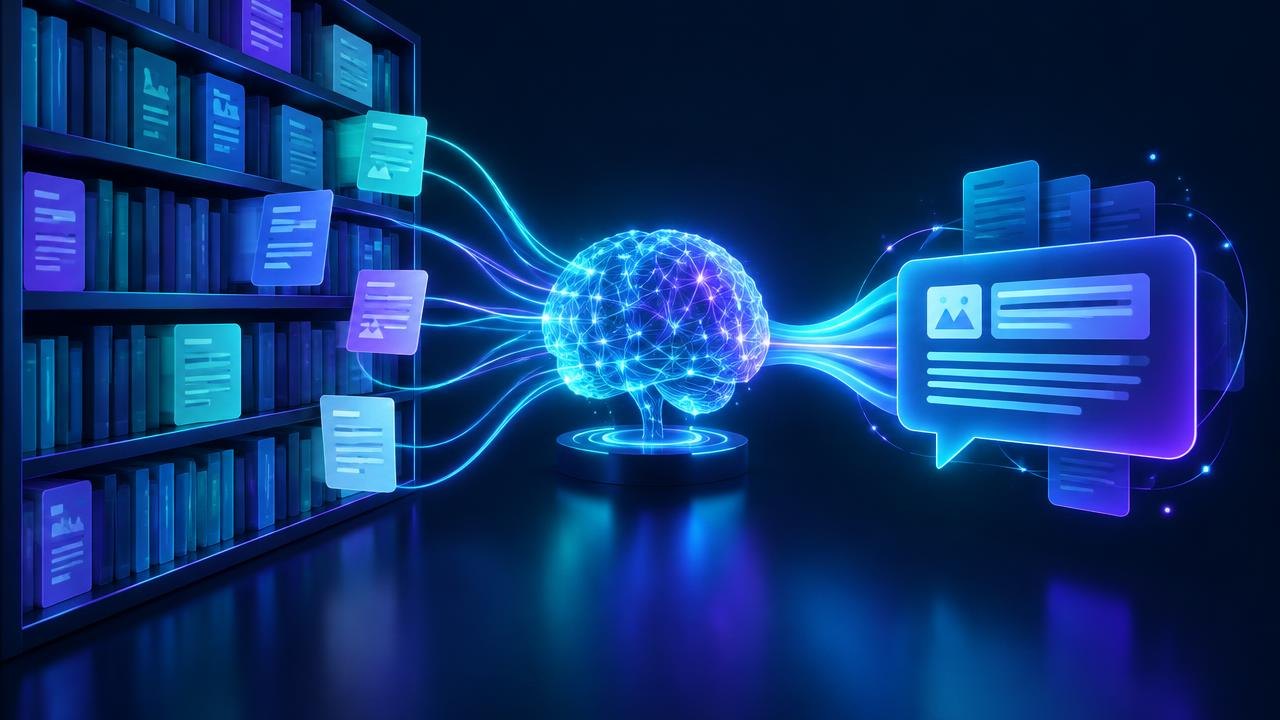
Retrieval-augmented generation, or RAG, helps a language model answer questions using information outside its training data. This guide follows the full path from source documents to a cited response, explaining where the method helps, where it fails, and how to judge whether it works.
How Does Retrieval-Augmented Generation Work?
RAG retrieves relevant information and supplies it as context when a language model generates an answer. It can use private documents, public pages, or structured records without retraining the model for every change. It does not guarantee correctness: retrieval, source quality, permissions, and the model's handling of evidence all affect the result.
Understand what RAG changes
A language model generates text from the input it receives and patterns learned during training. Without a retrieval mechanism, it has no automatic way to inspect your latest internal policy or a newly updated product record. RAG adds a lookup step so the response can use external evidence at request time.
The original RAG paper explored combining a generative model with retrieved non-parametric information. In practical applications, the broader pattern is straightforward: find evidence, package it with the question, and ask the model to answer from that evidence. Implementations vary considerably.
RAG does not require a vector database. Retrieval can use keyword search, semantic search, a structured query, or a combination. Microsoft's RAG overview describes the search-and-generation pattern and the role of an external knowledge source. Choose retrieval to match the information need rather than treating embeddings as a mandatory first step.
RAG also differs from fine-tuning. Fine-tuning changes model parameters to influence behavior; RAG changes the information supplied with a request. They can work together, but attaching a new document to a searchable corpus is not the same operation as teaching a model a new response style through training.
Prepare the evidence before a question arrives
Most document-based systems have an offline ingestion pipeline. It collects approved content, extracts text, separates useful units, attaches metadata, and builds a searchable representation. Good extraction preserves headings, table relationships, dates, and source identifiers rather than flattening everything into a context-free block.
Chunking divides documents into portions that retrieval can return. A chunk should contain enough context to make sense while remaining focused enough to match a specific question. There is no universally best chunk size. A troubleshooting procedure, a short policy clause, and a spreadsheet table need different handling.
When semantic search is used, an embedding model converts each chunk into a vector. Store the embedding version with the record, because later queries must use a compatible representation. Keep a reference to the original source and any heading or page information needed for a meaningful citation.
Permissions belong in this pipeline too. A private document should carry the metadata required to restrict retrieval to authorized people. Updating content without updating its permissions creates a dangerous mismatch: the text may be accurate while access is wrong.
Plan refresh and deletion behavior. A scheduled crawler, an event-driven update, and an on-demand database lookup have different freshness properties. Calling a system “live” does not establish that a newly changed source is already searchable, or that a deleted copy has disappeared from caches and indexes.
Follow a question through the runtime pipeline
At request time, the system may first normalize the question or generate a search-oriented version. Rewriting can resolve terminology, but it can also remove an important constraint. Preserve the original question and inspect rewritten queries during debugging.
Next, retrieval returns candidate evidence. Keyword search can find exact product codes; semantic search can match different wording for the same concept. Hybrid approaches combine signals. A reranker can then reconsider candidates using a more detailed relevance assessment before a smaller set reaches the generation step.
| Stage | Main job | Typical failure |
|---|---|---|
| Query preparation | Express the information need | Loses a date or product qualifier |
| Retrieval | Find eligible candidate evidence | Misses the authoritative document |
| Reranking | Prioritize the most useful candidates | Promotes a superficially similar passage |
| Context assembly | Fit evidence into the input budget | Cuts off a critical exception |
| Generation | Answer using the supplied evidence | Adds an unsupported claim |
| Verification | Check support and presentation | Accepts a citation that does not support the sentence |
Context assembly is not simply concatenation. It should remove unnecessary duplication, retain source boundaries, and make relevant dates visible. More retrieved text can worsen the answer if it adds contradictions or crowds out the passage that actually resolves the question.
The model then receives instructions, the user's question, and the selected evidence. Source text should be treated as data, not as authority to override system rules. The response policy should say what to do when evidence is incomplete, contradictory, or absent, including when to ask for clarification or decline to guess.
Work through a practical example
Imagine a hypothetical company whose travel policy changed in April. An employee asks, “Can I claim dinner when my train is delayed?” The system searches approved travel guidance and retrieves a current reimbursement clause, an older policy, and a discussion thread about a previous claim.
The strongest pipeline identifies the current approved clause as authoritative, checks the employee's access, and excludes the obsolete version from the answer context or clearly marks it as superseded. It retains the clause's conditions, such as required documentation, rather than extracting only the sentence containing “dinner.”
The model can then explain the qualifying conditions and cite the relevant policy location. If the policy does not cover the employee's situation, it should say so and point to the appropriate decision maker. RAG should not manufacture a spending limit or turn a coworker's anecdote into company policy.
Now suppose the current clause never appears in the retrieved results. A well-written generation prompt cannot reliably repair missing evidence. The investigation belongs upstream: extraction, chunking, metadata, query wording, or ranking may be responsible. This separation makes debugging more productive than repeatedly changing the final prompt.
Evaluate evidence and answers independently
Create a small evaluation set from realistic questions, including straightforward requests, ambiguous wording, unavailable answers, and permission-sensitive cases. Record what evidence would be sufficient for a correct answer. Human review is especially valuable when the relevant passage depends on domain judgment.
First ask whether retrieval found the needed evidence. Then ask whether the response used it correctly. A correct-looking answer produced without the right source may be a lucky guess; a poor answer produced with good evidence points to context assembly or generation rather than search.
Measure citation support at the claim level. A valid link is not enough if the linked paragraph does not support the associated statement. Check omissions too: an answer that repeats the main rule but excludes an important exception can mislead without containing an obviously false sentence.
For a hypothetical evaluation, suppose 20 questions require a particular policy clause and retrieval finds it for 15. Before improving the prose of those answers, examine the five missed cases. This is an illustrative diagnostic, not a quality benchmark or a claim about expected RAG performance.
Retain versioned evaluation results when changing chunking, embeddings, prompts, or ranking. Review failure categories rather than relying on a single aggregate score. Improvements for broad semantic questions can accidentally weaken exact-identifier lookup or access-sensitive queries.
Set limits for freshness, safety, and cost
RAG can make source updates available without retraining, but freshness still depends on ingestion delays, index refresh, and caching. Show source dates where they matter, and establish an explicit policy for which source wins when documents disagree. The newest timestamp is not always the most authoritative approval.
Retrieved content can contain malicious or irrelevant instructions. Treat it as untrusted input and keep authorization and tool permissions outside the model's discretion. A document saying “ignore previous instructions” should be handled as document text, not as an operational command.
Cost includes ingestion, storage, retrieval, reranking, input context, and output generation. RAG is not automatically cheaper than fine-tuning, and the two approaches often address different goals. Keep enough context to answer reliably, then evaluate whether additional stages earn their latency and operating expense.
Provide a fallback path. For important internal decisions, that might be a link to the source plus a human contact rather than an automated conclusion. The aim is dependable access to evidence, not producing a confident paragraph for every possible question.
Questions About Retrieval-Augmented Generation
Can RAG answer questions across several documents?
Yes, if retrieval finds the required pieces and the model can combine them correctly. Multi-document questions need evaluation for missing conditions, inconsistent dates, and unsupported connections between sources.
Does adding citations prove an answer is correct?
No. Citations improve inspectability only when they resolve to the right source and actually support the claim. Validate the relationship between the sentence and the evidence, not just the existence of the link.
Should the model always answer from the retrieved text?
For a source-grounded assistant, it should follow an explicit evidence policy. If the available material does not answer the question, a clear limitation or clarification request is preferable to filling gaps silently.
Can RAG use structured business data?
Yes. A controlled query can retrieve authorized records and supply the relevant results as context. Numerical questions may also require deterministic calculations rather than asking a language model to infer totals from prose.
Ground Generated Answers in Retrieved Context
RAG is a chain of evidence-handling decisions, not a cure for every model error. Improve the stage responsible for the failure and keep the user's ability to verify the result central to the design.
Next steps: Use the vector database selection guide for storage decisions, review the fine-tuning checklist for behavior changes, or browse advanced guides.
Sources
- Lewis and colleagues, arXiv — Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
- Microsoft Learn — Retrieval Augmented Generation (RAG) in Azure AI Search
This guide is general education, not professional security or implementation advice.