
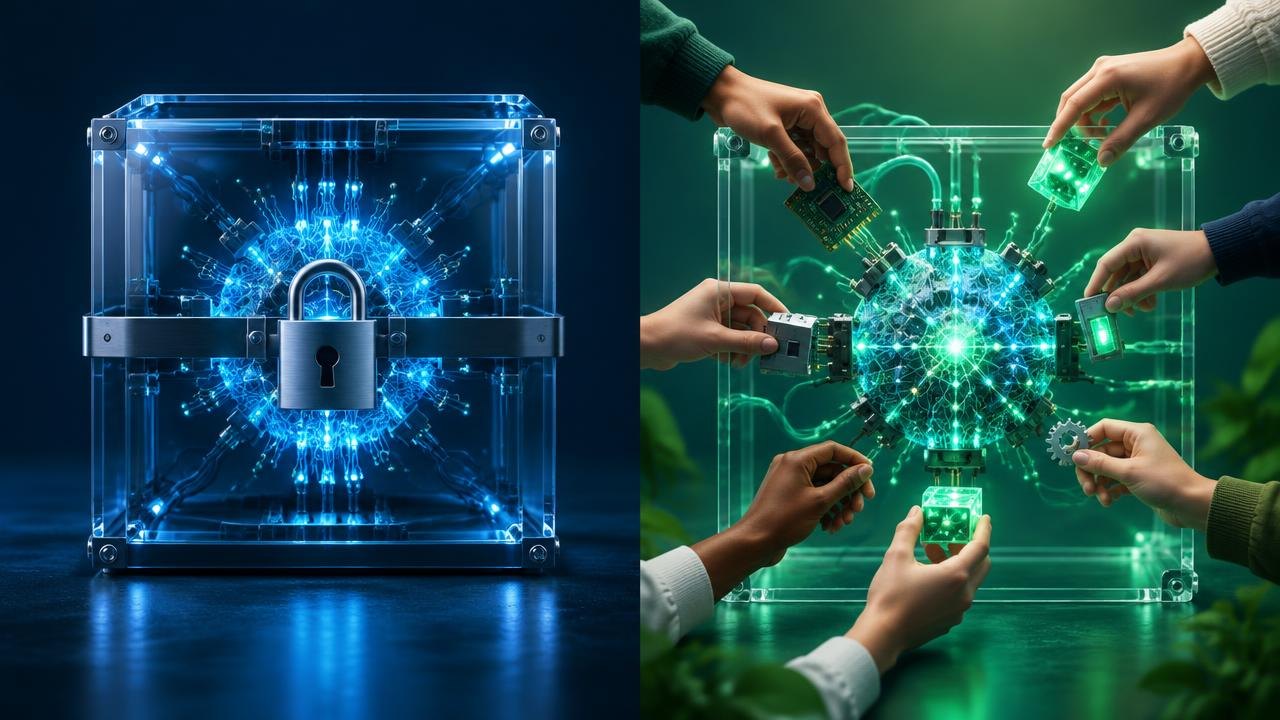
Choosing between proprietary and open-source AI is a decision about operating responsibility, not just model quality. This guide explains what you gain, what you still need to manage, and how to compare options against a real business task rather than a product demonstration.
Should You Choose Proprietary or Open-Source AI?
Choose a managed proprietary service when its quality, contractual terms, and operational convenience fit your workload. Consider a downloadable model when control over deployment or customization justifies maintaining the surrounding infrastructure. Neither approach guarantees better privacy, lower cost, or more accurate answers; compare the complete system and verify its license.
Separate the model license from the hosting arrangement
A proprietary model usually comes with provider-controlled access and restrictions on inspecting or modifying its underlying parameters. An open-source model should come with meaningful rights to use, study, modify, and redistribute the relevant components. However, a downloadable set of model weights is not, by itself, evidence that every component is open source or unrestricted.
Treat “open weights” as a description of availability, not a substitute for reading the license. Check commercial-use permissions, redistribution rules, attribution requirements, and any acceptable-use conditions. Also identify whether the tokenizer, serving code, and any adapters have separate licenses. Ask qualified counsel about ambiguous terms before making a material commitment.
Hosting is a separate decision. A downloadable model can run on a rented cloud server, an external managed platform, or equipment you operate. A managed endpoint can therefore serve an openly available model. Conversely, buying access to a proprietary service does not necessarily mean using a public consumer chatbot.
This distinction matters because the actual privacy boundary follows the deployment. Sending a prompt to an externally hosted open model still sends data to another organization. Running a model internally can reduce that particular disclosure, but only if logs, monitoring, support access, and connected tools remain within approved boundaries.
Compare responsibilities, not slogans
Use this table to prepare questions for suppliers and internal operators. These are evaluation categories, not promises about every product.
| Decision area | Managed proprietary service | Self-hosted downloadable model |
|---|---|---|
| Model access | Governed by service terms and interface | Governed by model and software licenses |
| Infrastructure | Provider operates the model service | Your team or contractor operates it |
| Customization | Limited to supported features | Depends on license, tooling, and resources |
| Data handling | Depends on contract and configuration | Depends on your entire deployment |
| Capacity | Subject to service quotas and availability | Subject to provisioned compute and scheduling |
| Changes | Provider may change versions or offerings | You choose upgrades and maintain compatibility |
| Exit effort | Export data and replace integrations | Preserve artifacts and replace infrastructure |
The move toward reusable language models did not remove the need to evaluate tasks individually. The dated research paper Language Models are Few-Shot Learners, published in 2020, illustrates that a language model can perform varied tasks through examples in its input. It is not evidence that every model can perform your task reliably or that one licensing approach wins.
Separate capability from convenience. A model may produce good drafts but lack the throughput you need. Another may be slower to deploy yet fit an offline workflow. A decision matrix should reflect the importance of each requirement rather than count features as equally valuable.
Define the workload before comparing models
-
Describe one job. Why: Broad goals such as “use AI in support” hide different risks. How: Specify the input, expected output, reviewer, and action taken afterward. Drafting a response for approval is different from issuing a refund automatically.
-
Classify the information. Why: The acceptable deployment may depend on what enters prompts. How: List personal information, confidential documents, credentials, and licensed content. Identify what can be removed or replaced before processing.
-
Set acceptance criteria. Why: A persuasive answer can still be wrong. How: Define required fields, factual checks, refusal behavior, and unacceptable errors. Use representative examples, including incomplete and contradictory inputs.
-
Specify operating constraints. Why: A model that works for one user might fail under concurrent demand. How: Record expected volume, peak concurrency, response-time limits, availability needs, and who handles incidents.
-
Name the accountable owner. Why: Responsibility otherwise falls between the application team and the model supplier. How: Assign someone to approve versions, review incidents, and stop the system when it behaves outside its approved scope.
Write these requirements before requesting proposals. Doing so makes a provider's missing feature visible and prevents a technically interesting deployment from becoming the default without a business reason.
Evaluate security across the whole application
Ask where prompts, outputs, uploaded files, and diagnostic records are stored. Check retention, deletion, training-use policies, regional processing, subcontractors, and support access. Obtain answers for the service tier and contract you would actually use, not a different product bearing the same brand.
For self-hosting, document how administrators authenticate, how secrets are stored, and how patches reach production. Restrict access to model endpoints and supporting databases. Downloaded artifacts and software dependencies need provenance checks and controlled updates, just as other production software does.
Cloud deployment still requires explicit allocation of responsibilities. CISA's Cloud Security Technical Reference Architecture, published in 2022, provides a security architecture reference for cloud adoption. Use that dated framework as a prompt to review identity, visibility, and operational controls, not as certification of a particular AI service.
A model connected to internal tools also needs limits on what it can do. Retrieved documents may contain misleading instructions; generated requests may ask for actions outside the user's authority. Apply permissions in ordinary application code, require approval for consequential actions, and do not treat a model's own assurances as authorization.
Calculate the cost of useful results
Compare total operating cost over the same period and workload. For a managed service, include usage charges, storage, retrieval, networking, application development, monitoring, and human review. For self-hosting, include compute, idle capacity, engineering time, updates, incident response, and replacement capacity.
Count retries and failed outputs. A cheaper model call may require several attempts or more reviewer time. Equally, a sophisticated model may be unnecessary when a small model meets a narrow acceptance test. Avoid assuming that customization automatically improves the economics.
Worked example — hypothetical numbers: A team needs 8,000 acceptable document summaries per month. Its managed option costs 900 budget units for inference and supporting services, plus 600 for review and operations: 1,500 total. A self-hosted option costs 700 for compute and 1,100 for maintenance and review: 1,800 total.
The corresponding costs are 1,500 ÷ 8,000 = 0.1875 units and 1,800 ÷ 8,000 = 0.225 units per acceptable summary. These are invented planning figures, not market prices. If volume changes, do not simply scale both totals linearly: staffing, capacity limits, and idle hardware can change the comparison.
Also estimate an exit budget. Record the time needed to replace an endpoint, migrate prompts, rebuild retrieval indexes, rerun evaluation, and retrain reviewers. Downloadable weights reduce some dependencies but do not eliminate reliance on hardware, serving libraries, or specialist skills.
Run a bounded pilot and retain an exit route
Use the same representative input set across candidates, with sensitive material removed unless processing has been approved. Score outputs against a written rubric rather than asking which sounds more impressive. Preserve model identifiers, settings, prompts, and evaluation dates so later comparisons have meaning.
Include difficult cases: missing context, ambiguous requests, long documents, unusual terminology, and instructions that should be refused. Measure time to a usable answer, not only time to the first response. Ask reviewers to record corrections and their severity.
Before wider deployment, rehearse an outage. Decide whether the application should queue requests, switch providers, or return a clear unavailable message. A fallback model must pass its own evaluation; it is not interchangeable just because it accepts similar requests.
Finish the pilot with a short decision record: chosen option, rejected alternatives, unresolved risks, owner, spending limit, and review trigger. Revisit the decision when the workload changes, the agreement changes, or measured quality deteriorates. Do not migrate solely because a new model attracts attention.
Questions About Proprietary and Open AI
Does downloading model weights make a model open source?
Not necessarily. Availability of weights does not establish the rights granted over the model or its supporting components. Inspect the actual license and documentation rather than relying on an informal label in a model directory.
Can a proprietary service use private company documents?
It may be suitable if its contractual protections, configuration, processing locations, and access controls satisfy your requirements. Get approval for the specific information involved. A generic statement that a service is “enterprise ready” does not settle the question.
Is fine-tuning necessary for company-specific answers?
Not always. Supplying approved reference material through retrieval or a carefully structured prompt may be enough. Fine-tuning changes model behavior through additional training; it is not a dependable substitute for an accurate, maintained source of company facts.
Can we switch between managed and self-hosted later?
Yes, but expect integration and evaluation work. Keep prompts, business rules, evaluation examples, and source documents portable. Model outputs and supported features differ, so a successful migration requires more than changing an address in a configuration file.
Weigh Control Against Operating Effort
Choose the arrangement your team can govern, afford, and operate reliably. Licensing, hosting, security, quality, and support belong in the same decision, but they are not the same question.
Next steps: Review how language models work, build a content verification process, and explore the AI News hub.
Sources
- arXiv — Language Models are Few-Shot Learners
- CISA — Cloud Security Technical Reference Architecture
This guide is general education, not professional, legal, or security advice.