
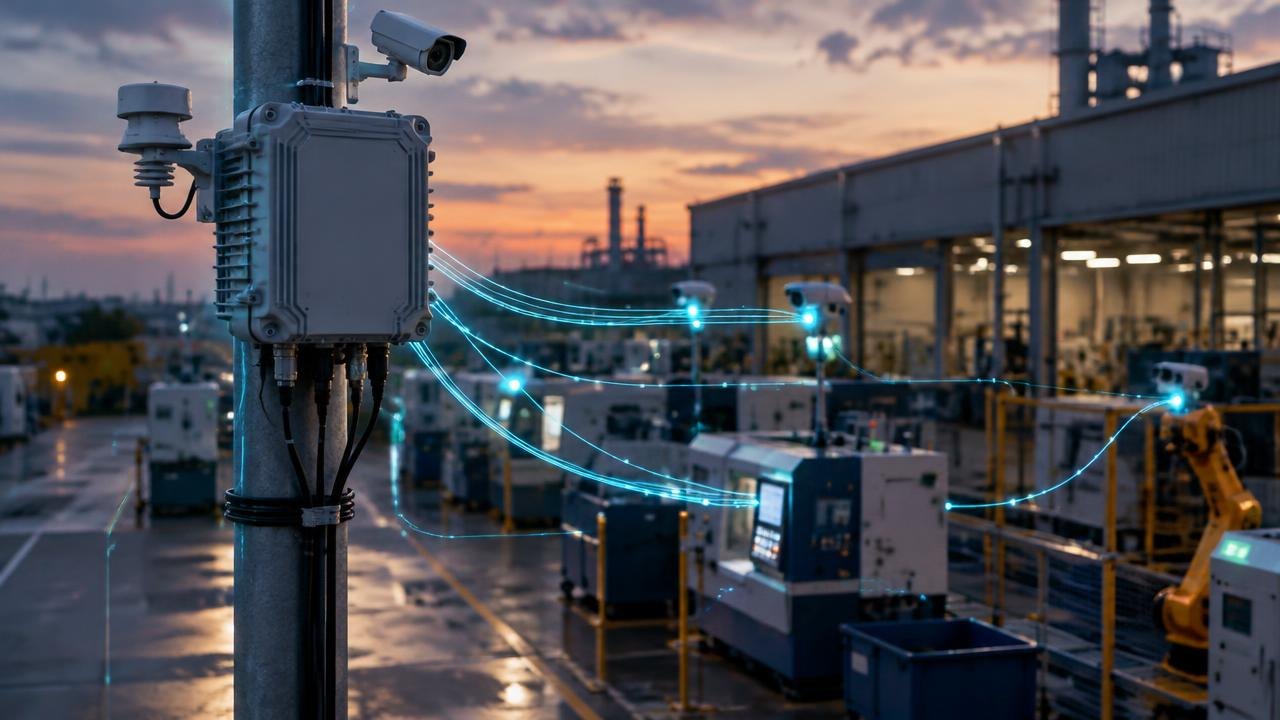
Edge computing moves selected processing closer to the devices and people producing data. This guide explains where that processing happens, when it helps, and how to evaluate a small deployment without assuming that every workload belongs outside the cloud.
What Is Edge Computing?
Edge computing runs some computation on a device, local gateway, or nearby server instead of sending every task to a distant data center. It can reduce network delays and the amount of data sent over a wide-area connection. Most useful designs combine local processing with cloud services, and neither speed nor security improves automatically.
What counts as the edge?
The edge is a location relative to a particular workload, not a special category of computer. A camera that detects motion internally, a gateway that combines readings from several machines, and a server inside a retail store can all perform edge computing. IBM's overview describes the approach as bringing applications closer to data sources, including connected devices and local servers.
Consider three common layers. A device collects information and may make a simple decision itself. A nearby gateway coordinates several devices or translates their messages. A cloud service stores longer histories, manages software, and supports analysis across locations. You do not need every layer, but identifying their responsibilities prevents vague architecture discussions.
Not every connected sensor is an edge computer. A sensor that only forwards measurements may have little processing capability. Likewise, putting an application in a different cloud region does not necessarily bring it close enough to meet a particular response requirement. Define proximity through measured performance and operational needs, not a vendor label.
The term also covers infrastructure deployed near users by network or content providers. That arrangement differs from owning a server in a factory, especially in who handles hardware and maintenance. Ask where computation actually runs and who operates it.
How local processing and cloud services work together
A typical workflow starts with data collection, followed by local filtering or analysis. The local system performs an authorized action, stores a temporary record, and sends selected results upstream. Cloud services can then aggregate trends, distribute configurations, or support a central dashboard. AWS explains how processing near data sources can support low-latency applications and reduce data movement.
For example, a machine-monitoring gateway might calculate vibration summaries locally. It sends routine summaries to a central service and uploads a longer diagnostic recording when an unusual pattern appears. This is not the same as deleting every raw measurement immediately: retention should match troubleshooting, contractual, privacy, and safety requirements.
The return path matters too. A cloud service might send an updated detection model, but the gateway should check its authenticity and compatibility before activating it. If an update fails, a known working version should remain available. A dashboard that shows the latest upload also needs a timestamp so operators can distinguish current conditions from stale information.
Decide which system owns the authoritative record. When both local and central systems accept edits, synchronization can create duplicates or conflicts. Giving events unique identifiers and defining how repeated messages are handled makes reconnection less risky.
Where edge computing helps—and where it does not
Start with a constraint that local processing can actually address. A slow cloud round trip, an expensive uplink, or a need to continue a limited workflow offline is a stronger reason than a general desire to modernize.
| Requirement | Possible edge benefit | Important limitation |
|---|---|---|
| Fast local response | Avoids a distant network round trip | Processing time and local congestion still matter |
| Large sensor or video streams | Sends summaries or selected events | Some raw records may still need retention |
| Unreliable internet | Keeps defined local tasks available | Cloud-dependent identity or APIs can still fail |
| Sensitive information | Can reduce raw data leaving a site | Local storage still needs protection |
| Cross-site reporting | Prepares consistent local summaries | Central aggregation remains useful |
Edge is less compelling when requests are infrequent, data volumes are small, and users already receive acceptable service from a hosted application. A conventional cloud service may be simpler to patch, observe, and restore. Local hardware also introduces purchasing, power, cooling, and replacement obligations.
Physical proximity does not establish a hard real-time guarantee. Industrial protection systems may require specialist engineering and certified components. Treat ordinary edge analytics as separate from safety-critical controls unless qualified professionals have designed the complete system for that purpose.
A worked example: monitoring a small workshop
Imagine a workshop wants to detect unusual vibration while keeping internet usage predictable. All figures in this example are hypothetical, not benchmark results or purchasing guidance.
Suppose ten machines each produce 2 megabytes of readings per minute. Uploading everything would produce 20 megabytes per minute, or 1,200 megabytes per hour, before protocol overhead. If a gateway instead sends a 0.02-megabyte summary per machine each minute, routine uploads become 0.2 megabytes per minute, or 12 megabytes per hour. Diagnostic recordings would add to that total.
The potential bandwidth reduction is substantial in this particular scenario, but it does not prove that a gateway saves money. The business still needs to account for hardware, support, installation, storage, and replacement. It also needs to confirm that summaries preserve enough detail to investigate faults.
Define behavior during an outage before deployment. The gateway could continue collecting readings and displaying a local warning while queuing summaries. It should have a storage limit, a clear policy for old records, and a visible indication that central reporting is disconnected. A local warning is not a substitute for an independently engineered emergency stop.
After connectivity returns, upload queued records in a controlled order. Avoid flooding the link or presenting old alerts as new emergencies. This reconnection behavior is part of the product, not an optional cleanup task.
How to evaluate a first deployment
-
Write a measurable problem statement. Why: A vague speed complaint cannot justify extra infrastructure. How: Identify the workflow, its current delay or data volume, and an acceptable range based on user needs. Measure the existing system before designing a replacement.
-
Draw the data path. Why: Hidden cloud dependencies can defeat offline operation. How: List each device, gateway, service, identity check, and storage location. Mark what remains available when the internet connection disappears and what should stop safely.
-
Assign workloads deliberately. Why: Local hardware has finite memory, storage, and processing capacity. How: Keep time-sensitive decisions nearby where justified; reserve broader reporting and resource-intensive analysis for central services when practical. Document why each component exists.
-
Pilot one representative location. Why: A successful demonstration on a desk may hide field constraints. How: Include normal load, peak load, power interruptions, failed updates, and reconnection. Compare response times and data transfer against the baseline using the same workload.
-
Define acceptance and ownership. Why: A technically successful pilot can still be impossible to support. How: Name the person responsible for updates, monitoring, physical replacements, and incident response. Decide what evidence would justify expansion or cancellation.
Include installation and recovery time in the evaluation. A small latency improvement may not be worth repeated site visits. Conversely, maintaining a critical local workflow during an outage may be valuable even when bandwidth savings are modest.
Security, privacy, and maintenance responsibilities
Keeping information nearby can reduce unnecessary transmission, but it does not automatically make the system private or compliant. A stolen gateway, exposed management port, or shared administrator password can create a serious problem. Local processing changes the risk distribution rather than removing risk.
Maintain an inventory of deployed devices, software versions, owners, and support dates. Limit administrative access, separate operational devices from general office traffic where appropriate, and protect data in transit and at rest. Use individual accounts and stronger authentication for management interfaces when supported.
Plan updates before deployment. Devices need authenticated software, a reliable delivery method, and a recovery path when installation fails. A device that cannot be patched or remotely diagnosed may become expensive to maintain. Restrict physical access where tampering could affect operations or expose stored information.
Also specify collection and deletion rules. Keeping every raw recording indefinitely can increase storage costs and privacy exposure. Retaining only summaries may make some investigations impossible. Choose deliberately, record the reason, and seek qualified advice when sector-specific duties or personal information are involved.
Questions About Edge Computing Basics
Does edge computing require an internet connection?
Some local functions can continue without one, provided their required data, software, and authorization are available locally. Remote dashboards, central synchronization, and third-party APIs may remain unavailable. Offline capability must be designed and tested rather than inferred from the word edge.
Is a phone an edge device?
It can be. A phone processing an image locally is doing computation close to the data source. The same phone may send another task to a cloud service, so the classification depends on the workload rather than the device alone.
Do I need artificial intelligence to use edge computing?
No. Simple rules, compression, filtering, and local database queries are all possible edge workloads. Machine learning is one option when its accuracy, resource requirements, and maintenance burden fit the problem.
Can edge computing lower the total bill?
Possibly, particularly when it avoids substantial data transfer or valuable downtime. Compare the full operating cost, including hardware lifecycle, software management, support, and site visits. Lower network usage alone is not a complete financial case.
Place Computing Where the Work Happens
Edge computing is useful when placing a specific task near its data source addresses a measurable constraint. Start with one workflow, define its failure behavior, and compare results with the simpler centralized alternative before expanding.
Next steps: Review the remote-work infrastructure checklist for related connectivity planning, explore How-To Guides, or browse the Guides section.
Sources
- IBM — What is edge computing?
- AWS — What is edge computing?
This guide is general education, not professional technical or security advice.