
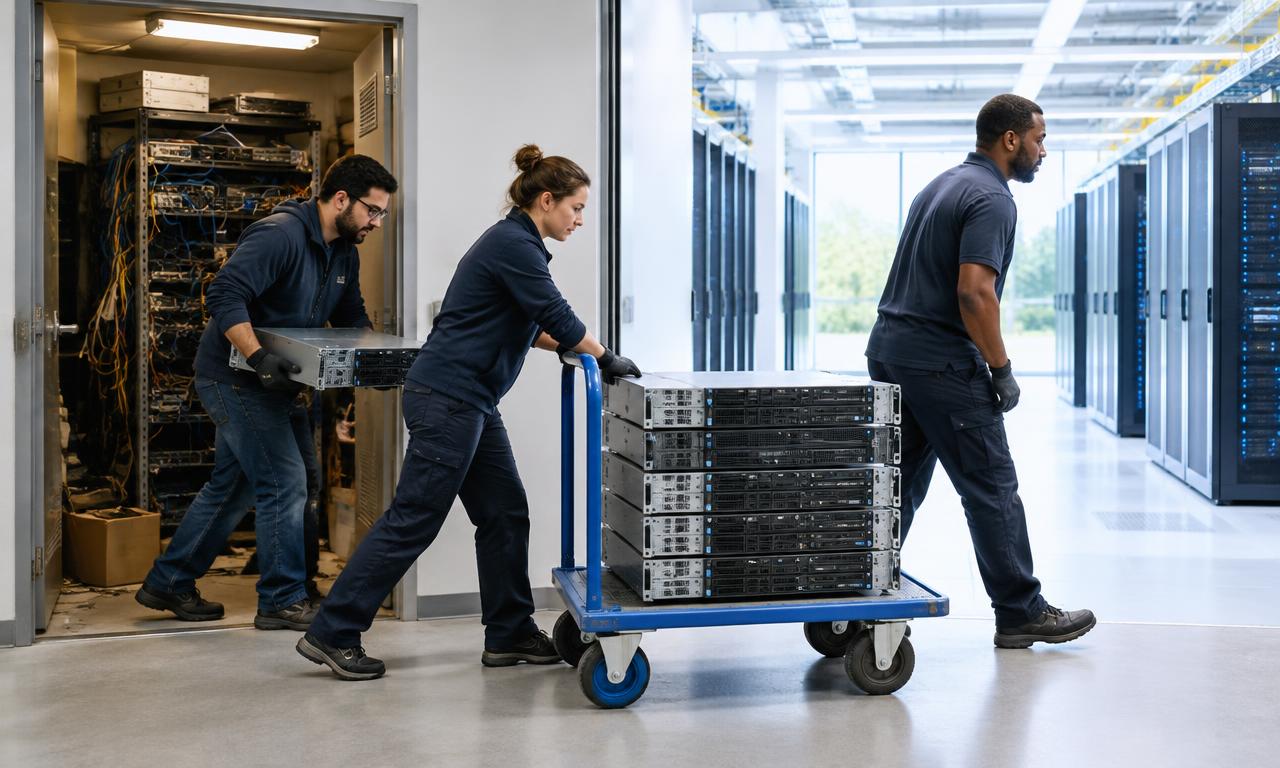
Moving hosting safely requires more than copying files to a new server. This checklist explains how to discover dependencies, prepare a secure destination, validate the application and execute a cutover with explicit recovery options.
How Do You Plan a Cloud Migration?
Inventory the application and its dependencies, establish recovery requirements and prepare a tested destination before changing production traffic. Rehearse data transfer, validate both business functions and technical behavior, and define who can approve or reverse the cutover. A migration is complete only when the new environment is stable, backups work and the old environment can be retired safely.
Establish scope, baselines and recovery objectives
-
Name the migration owner. Why: Unclear authority slows decisions during an incident. How: Identify the person coordinating the move, the technical operators and the business contact who can approve downtime or a rollback.
-
Measure current behavior. Why: A destination cannot be judged without a baseline. How: Record representative CPU, memory, storage, request volume, error rates and response times, including busy periods. Avoid sizing solely from an idle snapshot.
-
Define acceptable loss and downtime. Why: Recovery choices depend on business consequences. How: State the recovery point objective, meaning acceptable data loss measured in time, and the recovery time objective, meaning the target time to restore service.
-
Set the boundary. Why: Moving a website may also affect email, scheduled jobs or external integrations. How: List included and excluded components, owners and assumptions, and confirm whether the migration changes only hosting or also software versions and architecture.
Separate essential migration work from optional modernization. Combining a hosting move with a major application rewrite makes failures harder to diagnose. Sometimes an upgrade is necessary for compatibility, but document it as an additional change with its own tests.
Discover dependencies and protect the source
Inventory application runtimes, databases, queues, object storage, certificates, secrets, firewall rules and scheduled tasks. Add external services such as payment processing, identity providers, email delivery and webhook recipients. Record version requirements and where configuration values currently live.
Check for assumptions hidden in code or deployment scripts. Hard-coded IP addresses, local file paths, time zones and environment-specific URLs can break a service even when the application starts successfully. Identify upload directories and other writable locations that must survive the move.
Take an appropriate backup before making disruptive changes, then prove that it can be restored. A successful backup job does not demonstrate a usable recovery. AWS's recovery testing guidance emphasizes testing recovery implementations rather than relying on an unexercised plan.
| Item | Evidence before cutover | Accountable role |
|---|---|---|
| Database | Restore and integrity checks completed | Database owner |
| Application files | Versioned deployment and upload inventory | Application owner |
| Identity | Required users and roles verified | Access administrator |
| Network | Intended routes and exposure tested | Infrastructure owner |
| External services | Callbacks and allowlists checked | Integration owner |
| Recovery | Written procedure rehearsed | Migration lead |
Protect backup access and avoid leaving the only recoverable copy in the same failure boundary as the system being changed. Geographic separation may support resilience, but location choices must also fit legal, contractual and recovery requirements.
Prepare a secure, observable destination
-
Build from documented configuration. Why: Undocumented manual setup is hard to repeat or recover. How: Record infrastructure settings and deployment steps, using automation where the team can maintain it safely.
-
Limit permissions and exposure. Why: Temporary migration access can become permanent risk. How: Use named accounts, suitable MFA, least-privilege roles and restricted administrative paths. Open only the network access the application actually needs.
-
Protect secrets and transfers. Why: Migration scripts and copied configuration can expose credentials. How: Use approved secret storage and encrypted transfer methods, verify certificate handling and rotate credentials if exposure is suspected.
-
Enable monitoring before production. Why: An application that appears available may be losing jobs or failing transactions. How: Collect infrastructure signals, application errors and business-relevant checks, with alerts routed to someone available during cutover.
CISA's MFA guidance supports adding protection beyond passwords. MFA is one control, not a substitute for reviewing broad roles, exposed databases or secrets embedded in files.
Keep responsibility boundaries explicit. A managed database or hosting service may handle some infrastructure maintenance while leaving application configuration, accounts and data recovery choices with your team. Ask who performs each operational task rather than assuming “managed” means everything.
Rehearse transfer and validate real workflows
Perform a trial migration into a non-production destination using appropriately protected data. Measure transfer duration and document dependencies in the order they must be restored. If a database export requires a compatible version or extension, resolve that before the cutover window.
Validate records using more than file size or row counts. Counts and checksums can support integrity checks, but business-level relationships matter too. Confirm that users, orders, attachments and permissions remain connected as expected.
Exercise login, search, uploads, notifications, background jobs and important integrations. Test failure behavior as well as success: rejected credentials, unavailable external services and interrupted jobs. Ensure the rehearsal does not send real customer messages or duplicate financial actions.
Run authorized performance tests representative of expected demand and compare them with your baseline. A server with similar specifications can behave differently because of storage latency, network paths or database configuration. Define an acceptable range rather than assuming newer infrastructure must be faster.
Finally, test restoration in the destination. Migration validation and recovery validation answer different questions: one checks whether the move worked; the other checks whether the new service can recover later.
Execute a controlled cutover with a data-safe fallback
Prepare a runbook containing exact actions, owners, verification points and stop conditions. State when changes are frozen, how the final data synchronization works and how users will be informed. Confirm that the people able to change DNS, deploy software and restore data are available.
For DNS changes, understand existing records and caching behavior. AWS's domain migration guide describes considerations such as record configuration and time-to-live settings. Lowering a TTL shortly before cutover does not erase records already cached under an earlier value.
Prevent uncontrolled writes to two independent copies of the database. Depending on the system, this may require a maintenance period, a read-only source or a carefully designed replication arrangement. The right method depends on the application's consistency requirements and the team's capabilities.
Consider a hypothetical shop planning a thirty-minute maintenance window. Its rehearsal shows that the final data sync takes eight minutes, leaving time for verification. These are invented planning figures, not a prediction for other systems. The team agrees to stop if integrity checks fail or the critical checkout test cannot complete.
A rollback must address new writes. If customers have created orders on the destination, simply pointing traffic back can lose or split those records. Define whether rollback remains possible after writes resume and how any new data would be reconciled. “Keep the old server” is not a complete recovery plan.
Stabilize, verify costs and retire the old environment
Watch errors, latency, resource use, queue depth and completed business actions after cutover. Include automated jobs that run less frequently than the initial smoke tests. Ask users to report anomalies through a defined channel rather than scattering observations across messages.
Compare actual charges with the migration estimate. Temporary duplication, log retention, backups and data transfer may increase spending during the transition. Confirm which resources remain necessary before deleting anything that supports recovery.
Revoke temporary credentials and remove migration-specific network access. Update operating documentation, monitoring ownership and backup procedures. Make sure the routine team can deploy, restore and obtain support without depending indefinitely on the migration specialist.
Retire the source only after agreed validation and retention conditions are satisfied. Preserve required records, remove obsolete DNS entries and securely dispose of data according to policy. Do not use an arbitrary number of days as the only criterion for shutdown.
Questions About Cloud Hosting Migration
Can we promise zero downtime?
Only if the architecture, transfer method and tests support that claim, and even then avoid treating it as risk-free. Many applications need a controlled write pause to preserve consistency. A planned, communicated interruption may be safer than an improvised attempt to maintain continuous writes.
Should we migrate email with the website?
Only if email is explicitly in scope. DNS zones may contain mail and verification records that must remain intact when web hosting changes. Inventory those records and coordinate with the email administrator before changing name servers or replacing a zone.
Is a snapshot enough for rollback?
Not necessarily. It may omit external files, dependencies or transactions written afterward. Verify what the snapshot includes, whether it is application-consistent and how restoration works. Define handling for post-cutover changes separately.
When is the migration officially finished?
When acceptance checks pass, routine operations and recovery are documented, and the source is either safely retired or retained under an explicit plan. A successful first page load is an early signal, not completion evidence.
Prepare Before Moving Workloads
A safe migration is a rehearsed change with clear data ownership and recovery boundaries. Treat cutover, stabilization and source retirement as separate decisions.
Next steps: Review cloud hosting basics, compare cloud providers, or explore the Cloud Hosting hub.
Sources
- AWS — Test disaster recovery implementation
- AWS — Migrating DNS for a domain in use
- CISA — Turn on MFA
This guide is general education, not professional purchasing or security advice.